Acoustic Token Admixture for Joint Speaker and Content Anonymization
Abstract
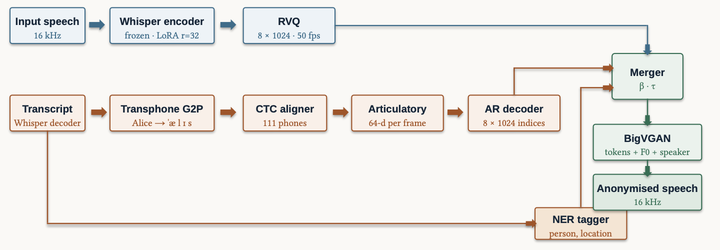
Speech recordings in regulated domains cannot be shared or reused for AI development without suppressing two independent re-identification channels: biometric speaker identity and linguistically identifying content. Existing approaches address each channel in isolation and require full re-synthesis, sacrificing the in-domain acoustic characteristics that make recordings valuable. We propose a unified acoustic token-space framework that jointly anonymizes both channels via per-frame admixture of encoder-derived and phoneme-conditioned tokens, with NER-triggered span replacement preserving surrounding prosody. On the VoicePrivacy 2024 benchmark the system achieves EER 42.54%, within one point of the challenge top submission, with WER 3.73%.
Type
Publication
In Proc. Interspeech 2026